Try the full interactive pipeline demo here (opens in a new tab)
Google recently announced Grounding With Exa Web Search for Gemini models.
This new grounding option, which is currently available in private preview on Vertex, uses Exa’s “Highlights” to extract query relevant text from a web page (or pages), leading to a significant reduction in input tokens.
Highlights is cool. And it looks like magic…
…but I was always the kid that was trying to peek up the magician’s sleeve. And I was skeptical about it being a single model doing all the work.
So I set about trying to reverse engineer it, and replicate it. Suffice to say, things got interesting.
And, spoiler: the demo video is a little misleading.
My Original Hypothesis (Based On Their Demo Video)
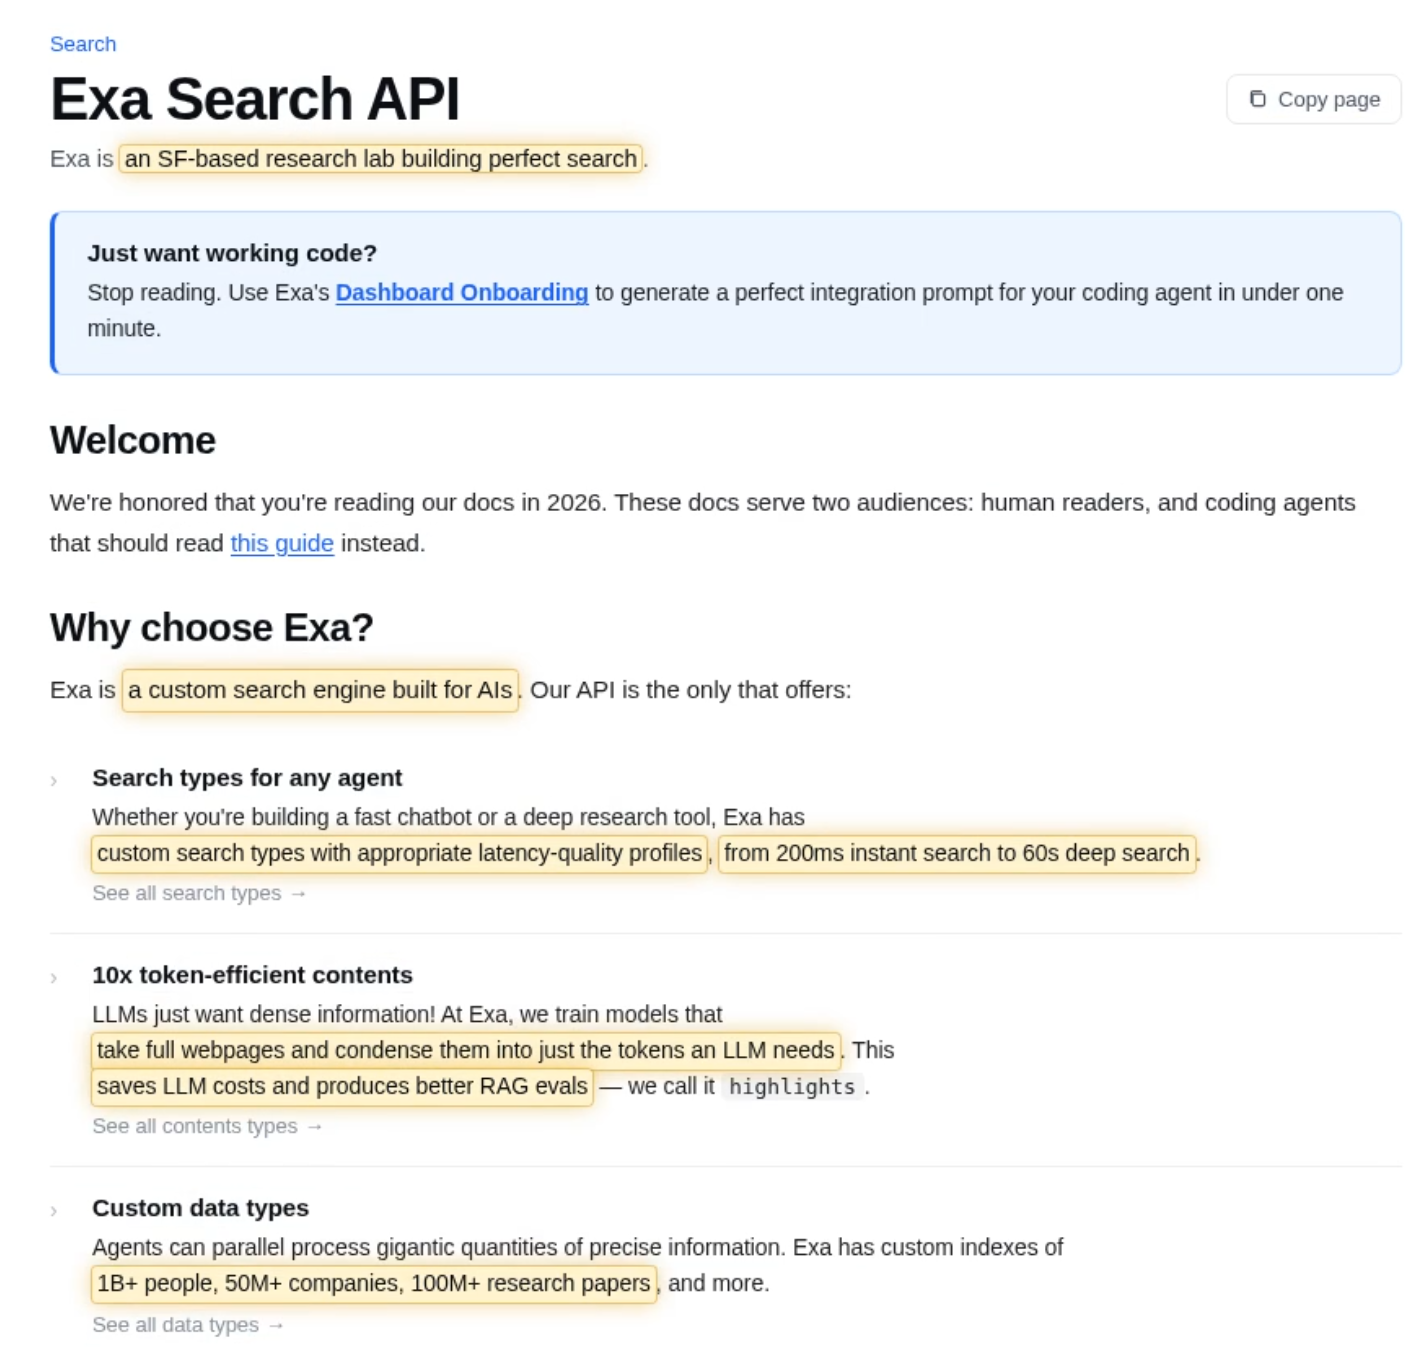
Watching the demo closely, and noticing that the highlights shown were all partial sentences/clauses, I formed an initial hypothesis about what Exa's "trained model" actually is. They claim their API returns highlights in <100ms. But inference over a 10K token document takes 50-500ms minimum.
So I figured they were doing something like:
- pre-computed sentence embeddings at index time,
- approximate nearest-neighbour lookup at query time,
- a lightweight re-ranker (cross-encoder) to score the top candidates,
- a clause boundary detector to trim sentences down to informative fragments,
- and some form of query classifier for routing.
And I set out to build V1 to emulate it.
V1: matching the Exa demo
I built the first version in a day or so, trying to replicate what the demo appeared to show, which again, was sub-sentence, clause-level highlights. My pipeline was:
- Fetch and clean — Firecrawl grabs the page as markdown, stripping navigation, headers, images
- Split into sentences — declarative prose only, filtered for length and quality
- Generate hypothetical answer (Split HyDE) — a cheap LLM generates a hypothetical answer (doesn't have to be right, just use the right words), split into individual sentences, each embedded separately
- Embed everything — batch embed all document sentences + HyDE vectors
- Score and rank — cosine similarity (max-sim across HyDE vectors) + n-gram keyword boost
- Extract clauses — isolate the informative complement clause from each top sentence
On SimpleQA (feeding the extracted highlights to an LLM for answer generation), this version scored 75% accuracy with ~397 tokens, beating full-page retrieval (65% at ~878 tokens) by 10 percentage points. I used a fast, cheap model (Gemini 2.5 Flash Lite) at every stage.
The clause extraction was working pretty well. Exa's demo showed inline sub-sentence fragments, so I built regex-based clause boundary detection: find the declarative verb, extract the complement. "Exa is a custom search engine built for AIs" → "a custom search engine built for AIs."
I was ready to publish. "Here's how Exa probably does it, here's our replication, here's the benchmark."
Then I tested their actual API...
V2: what I built after seeing the truth
The API results (below) revealed that Exa isn't doing sub-sentence extraction at all. Their demo runs against their own docs page, where section boundaries happen to look like clause-level highlights. On real prose, they often return section-level blobs.
This changed the problem. Instead of trying to match their demo, I could build what the demo claims to do. The pipeline evolved:
- Fetch and clean — now retaining heading structure for analysis
- Classify retrieval strategy — a single lightweight LLM call reads the page's heading outline and decides the optimal extraction approach (this is new — and probably what Exa's "trained model" aspires to)
- Early exit or full pipeline — the classifier determines what happens next:
- HEADINGS_DIRECT → return the heading text as the answer. No embeddings, no scoring. Done.
- SECTION_PROSE → retrieve the target section's content directly. No embeddings needed. Done.
- FULL_EXTRACTION / FULL_EXTRACTION_TRIPLES → run the full V1 pipeline (split, HyDE, embed, score, rank), optionally with triple extraction on top
The output is scored highlights in three formats (sentences, clauses, triples) — not answers. Answer generation is the consumer's job. We generate answers in the demo to prove the highlights are groundable, but that's not part of the extraction pipeline itself.
The key additions: adaptive routing (the classifier) and structured compression (semantic triples). Each emerged from testing against real content and finding where the V1 pipeline fell short.
What Exa's API actually returns
I signed up, got an API key, and ran the same queries against their highlights endpoint. The results weren't what I expected.
| 0.803 | The Last Jedi feels less slavish than The Force Awakens did. |
| 0.801 | a pure success, accessing the molten core of its drama and grappling with it in nuanced ways |
| 0.800 | connect with many a die-hard and newbie alike, I suspect |
| 0.796 | with this ever-so-slightly lopsided movie, that alone is enough to make The Last Jedi a classic |
| 0.675 | Johnson expands the psychology of Star Wars, bringing shading and moral ambivalence |
FULL_EXTRACTION_TRIPLES — opinions scattered throughout the review| 0.816 | On any trip to Japan, expect to carry any on-the-go trash with you until you return to your accommodation |
| 0.795 | In Japan, it's considered bad form to eat in public, especially while walking. |
| 0.790 | quickly notice how few public garbage cans are present on streets in Japan |
| 0.740 | To pay as the Japanese do, place your cash or card in the small tray at the register |
FULL_EXTRACTION — etiquette tips distributed across multiple sections| 0.800 | a game played between two teams of nine players each |
| 0.776 | also put out if he strikes out, or fails to hit the baseball three times after three good pitches |
| 0.767 | divided into nine innings, each divided into two halves |
| 0.749 | The batter attempts to hit the ball with the bat to a location out of the reach of the defensive players |
FULL_EXTRACTION — basic concepts spread across the article- 1. Maximizer CRM
- 2. HubSpot CRM
- 3. Salesforce
- 4. Zoho CRM
- 5. Pipedrive
- 6. Freshsales
- 7. Monday.com CRM
- 8. Microsoft Dynamics 365
- 9. Capsule CRM
- 10. Less Annoying CRM
HEADINGS_DIRECT — heading text IS the answer. Zero extraction needed.SECTION_PROSE — heading "Do LLMs Build Knowledge Graphs from Your Website?" is a question that points to the answer underneath it.| 0.861 | OpenAI was founded in 2015 in Delaware as a nonprofit. |
SECTION_PROSE → "Founding" section 28 tokensSECTION_PROSE → FAQ heading "Why does content depth matter separately from structural depth?"| 0.830 | Exa is a custom search engine built for AIs. |
| 0.809 | custom indexes of 1B+ people, 50M+ companies, 100M+ research papers |
| 0.759 | models that take full webpages and condense them into just the tokens an LLM needs |
| 0.758 | Web retrieval with highlights — search the web in real time |
| 0.718 | from ~250 ms instant search to 12-40 second deep-reasoning search |
FULL_EXTRACTION — broad overview query, needs full page sweepThe demo is a presentation layer
So how does their demo video show those polished, inline clause-level highlights?
Look closely at the video. It's running against their own documentation page. I ran the same query against their API. Here's what it returns:
This is actually good output for this page. The [...] markers separate meaningful chunks: the page title, the value proposition, the search types table. Their frontend splits on [...], does substring matching against the rendered page, and highlights each chunk inline with a yellow box. On a docs page, where headings, bullet points, and table rows ARE the key information, each highlighted chunk maps to a real information unit.
That's why the demo looks like intelligent clause-level extraction. It is, effectively, on this kind of page. The structure of the content and the structure of the output happen to align.
Running my pipeline against the same page with the same query, "tell me about the Exa Search API.", our classifier correctly identified this as a broad overview query and routed to FULL_EXTRACTION since no single section holds the answer. The pipeline then extracted 10 scored highlights from across the page and produced this grounded answer:
Both approaches work on this page. Exa preserves the table format with latency figures, information that's naturally tabular. Our pipeline produces a grounded answer from 78 tokens of triples. Different strengths: Exa keeps structure, we produce synthesis. On a well-structured docs page, both are valid.
The problem is that this is the best case, not the general case. On prose — reviews, guides, educational content — the same approach often returns one section blob instead of extracting the specific information the query asks for. The demo showcases the content type where section selection works best and presents it as the general capability.
The adaptive classifier: doing what Exa's "trained model" claims to do
The concept behind Exa's approach is sound. Not all queries need the same extraction method. A listicle query should grab headings. A factoid should find the right paragraph. An opinion question needs to sweep the whole article. Their "trained model" is presumably trying to learn this routing. I built it explicitly: a single lightweight LLM call (~1.4s) that reads the page's heading outline and decides what to do.
Four strategies
| Strategy | When | What happens | Cost |
|---|---|---|---|
| HEADINGS_DIRECT | Heading text IS the answer (product lists, step names, features) | Return headings directly, skip extraction entirely | Free (0 extra LLM calls) |
| SECTION_PROSE | Answer in body text under a specific heading (FAQ, definitions) | Retrieve that section's content directly | 1 cheap LLM call |
| FULL_EXTRACTION | Answer scattered across sections (summaries, overviews) | Full HyDE + embed + rank pipeline | Standard pipeline |
| FULL_EXTRACTION_TRIPLES | Scattered facts needing entity disambiguation (reviews, opinions) | Full pipeline + triple extraction | Standard + 1 cheap LLM call |
The classifier prompt is explicit about the distinction that trips up simpler approaches:
- "Maximizer CRM" as a heading →
HEADINGS_DIRECT(the heading IS a list item) - "Do LLMs Build Knowledge Graphs?" as a heading →
SECTION_PROSE(the heading is a QUESTION pointing to its answer)
Exa's model can find the right section on structured pages. In the CRM test it correctly located the product list area. But it doesn't always distinguish between these content types, often returning the same kind of section-blob output whether the headings are the answer or merely point to the answer. The classifier understands that distinction.
Why this matters for cost
On a listicle page, the classifier returns the answer in ~1.4 seconds with zero additional API calls. No embeddings, no sentence splitting, no scoring, no answer generation. Just the headings.
On a prose-heavy review, it routes to the full pipeline + triples, spending the extra 1.3 seconds on triple extraction because the content type demands it.
On an FAQ page, it identifies the single section with the answer and retrieves just that paragraph — ~50 tokens instead of the full pipeline's ~150.
The pipeline adapts to the content.
We generate grounded answers in our demo to show that the highlights are groundable. To demonstrate that 70 tokens of structured triples can produce an answer as good as one from the full article. But in a production pipeline, you'd return the highlights and let the consumer's model do the synthesis.
The demo generates multiple answer variants concurrently (from clauses, from triples, from the classifier's section) so you can compare them side-by-side. That's a demonstration tool, not architecture. In production, the classifier would pick one extraction strategy, the pipeline would run that strategy, and the highlights would come back.
The compression cascade
This is the core architecture insight. It's not one model doing everything. It's a cascade where each stage does what it's best suited for:
- Classifier (~100 tokens input): 30 headings → routing decision in 1.4s
- Embeddings + cosine similarity (free after initial embed): 2,000 words → ~160 tokens of ranked sentences
- Cheap model (~250 input tokens, fractions of a cent): 160 tokens → ~70 tokens of structured triples
- Frontier model (the expensive one): only ever sees 70 tokens of fact-dense, disambiguated input
The frontier model never touches the full article. It gets pre-chewed structured facts with explicit subjects, so it can't hallucinate referents or lose track of what "it" refers to. Each stage does the work it's best suited for — the classifier for routing, embeddings for relevance ranking, a cheap LLM for syntactic restructuring, the frontier model for reasoning and synthesis.
Three levels of extraction granularity
The triples are generated by a single lightweight LLM call (~1.3s) on the top-ranked sentences. Format: entity | relationship | fact. Here's what the pipeline produces for each test case:
The Last Jedi | feels less slavish than | The Force Awakens
The Last Jedi | laid out | long and intricate plot
The Last Jedi | is | a classic
The Last Jedi | is | a pure success
Johnson | expands | the psychology of Star Wars
Baseball game | is divided into | nine innings
Pitcher | throws the ball toward | a member of the offensive team at home plate
Batter | attempts to hit | the ball with the bat
Run | is a score made by | an offensive player who has rounded the bases
Home Run | is a play in which | the batter makes it safely around all bases without stopping
shoes | must be taken off | frequently at religious sites
comfortable walking shoes | are a must | for any visit to Japan
toilet slippers | are dedicated | in shoes-off establishments
trash | carry | until accommodation
Japanese | big on | queues
Compression across test cases
| Page | Original | Best output | Compression | Answer quality |
|---|---|---|---|---|
| 301 Redirects | 5,492 words | 52 tokens triples | 99.1% | Good |
| Japan Etiquette | 1,914 words | 56 tokens triples | 97.1% | Better from triples |
| Last Jedi Review | 2,067 words | 63 tokens triples | 96.9% | Better from triples |
| Baseball Rules | 2,195 words | 109 tokens triples | 95.0% | Equal |
| CRM Listicle | 1,500+ words | 22 tokens headings | 98.5% | Perfect — headings ARE the answer |
| QueryBurst FAQ | 800+ words | ~50 tokens section | 93.8% | Precise — one paragraph |
| OpenAI Wikipedia | 19,759 words | 28 tokens section | 99.9% | More precise than Exa (includes month) |
The architecture (for those who want to build it)
Split HyDE
Standard HyDE generates a hypothetical answer and embeds it as one vector. This collapses multiple elements into a single point in vector space.
Split HyDE: generate one answer, split into individual sentences, embed each separately. Score document sentences by their maximum similarity to any HyDE vector.
If the hypothetical answer mentions features AND pricing, each gets its own vector. Document sentences about features match the features vector; sentences about pricing match the pricing vector. Neither is diluted by the other.
Hybrid scoring
Cosine similarity + n-gram keyword boost. Pure embeddings miss obvious term matches. Pure keywords miss meaning. The combination handles both.
Retrieval strategy classifier
A single LLM call reads the document's H2/H3 heading structure (indexed by ID) and selects the optimal extraction strategy. The key insight is the distinction between headings that are answers (product names in a listicle) and headings that point to answers (questions in an FAQ). This simple routing decision determines whether the pipeline runs at all.
The prompt is explicit: "NEVER use HEADINGS_DIRECT for headings that are questions or topic labels — those POINT TO answers, they are not answers themselves."
Grounded synthesis
Feed only the extracted highlights (or triples) to an LLM with strict instructions to answer from the provided text alone. The constraint helps to reduce hallucination since there's nothing to hallucinate from.
The triples-grounded answers are consistently as good or better than the clause-grounded answers, despite using 40-60% fewer tokens as input. This is because each triple has an explicit subject. The LLM doesn't need to resolve anaphora or track context across fragments.
What I replicated, and what I added
| Capability | Exa | Our Pipeline |
|---|---|---|
| Find relevant page section | Yes | Yes (+ classifier routing) |
| Sub-sentence extraction | Within-section skipping via [...], fragments often broken | Yes (clauses + triples) |
| Per-passage scoring | Empty array | Yes (cosine + n-gram, 0–1) |
| Multiple highlight formats | No | 3 levels (sentences, clauses, triples) |
| Adaptive strategy | Implicit (opaque model) | Explicit (4 named strategies) |
| Structured output | Text blob | Scored highlights + typed triples |
| Works on prose/opinions | Poorly (single section, often intro) | Yes (extracts across full page) |
| Works on listicles/structured | Yes (finds right area, messy output) | Yes (clean headings list, no extraction needed) |
| Grounded answers | No (highlights only) | Yes (from clauses, triples, or section) |
| Latency | Sub-second pre-indexed, ~3s fresh | ~3s cached, 5–15s uncached |
| Cost per query | Opaque | ~$0.001 (3–4 cheap LLM calls + embeddings) |
The latency gap is real for pre-indexed pages. Exa has pre-computed embeddings for billions of pages, giving them sub-second retrieval. But on fresh pages (not in their index), Exa takes ~3 seconds too. They're computing embeddings on the fly just like we are. The gap is their index coverage and their hardware stack, not a fundamentally faster architecture. With pre-computed indices, local models (and a non potato server), our pipeline would be much closer to their cached speed.
The production path: from LLM classifier to trained model
The ~1.4 second classifier latency is an artefact of using an off-the-shelf LLM for routing. The input signal is simple; a query string and a flat list of headings. In production, this is a textbook distillation target:
- Bootstrap labels — the LLM classifier generates its own training data. Every query it processes is a labelled example: (query, heading outline) → strategy. Accumulate a few thousand, have humans verify the edge cases.
- Train a small model — a fine-tuned BERT, a lightweight encoder, or even logistic regression on heading features (count, depth, question-mark presence, list patterns, heading-to-content ratio). The decision boundary isn't complex.
- Swap in — the trained model replaces the LLM call. Latency drops from ~1.4s to <10ms. Cost drops to zero per query. The rest of the pipeline stays identical.
This is almost certainly the path Exa took for their "trained model". The classifier concept is the same; the difference is what happens after routing.
The LLM version is the right starting point: it validates the strategy taxonomy, handles long-tail cases gracefully, and generates labelled data as a side effect of running. The trained model is the obvious optimization once you've proven the routing works.
Build it yourself (code examples)
Here's a complete, standalone Python script that implements a simplified version of the full pipeline. It uses Firecrawl for page fetching, Google's Gemini for embeddings and LLM calls, and numpy for scoring. Swap in any embedding provider and LLM — the architecture is the same.
"""
Highlights extraction pipeline — standalone implementation.
Requires: pip install google-genai numpy requests
Set env vars: FIRECRAWL_API_KEY, GEMINI_API_KEY
"""

import re, os, numpy as np, requests
from google import genai
from google.genai import types

# --- Config ---
FIRECRAWL_KEY = os.environ["FIRECRAWL_API_KEY"]
GEMINI_KEY = os.environ["GEMINI_API_KEY"]
EMBED_MODEL = "gemini-embedding-001"
LLM_MODEL = "gemini-2.0-flash-lite"
TOP_K = 10
NGRAM_BOOST = 0.03


# --- 1. Fetch page as markdown via Firecrawl API ---
def fetch_page(url: str) -> str:
    resp = requests.post("https://api.firecrawl.dev/v1/scrape", json={
        "url": url,
        "formats": ["markdown"],
        "excludeTags": ["header", "footer", "nav", "form", "aside", "img"],
    }, headers={"Authorization": f"Bearer {FIRECRAWL_KEY}"})
    resp.raise_for_status()
    return resp.json().get("data", {}).get("markdown", "")


# --- 2. Split into sentences ---
def split_sentences(markdown: str) -> list[str]:
    lines = markdown.split("\n")
    sentences = []
    for line in lines:
        line = line.strip()
        if not line or line.startswith("#") or line.startswith("|"):
            continue
        line = re.sub(r"\[([^\]]+)\]\([^)]+\)", r"\1", line)  # strip links
        line = re.sub(r"[*_]{1,2}", "", line)  # strip bold/italic
        for sent in re.split(r"(?<=[.!?])\s+", line):
            sent = sent.strip()
            if len(sent) > 30 and len(sent) < 500:
                sentences.append(sent)
    return sentences


# --- 3. Split HyDE ---
def generate_hyde(query: str, client: genai.Client) -> list[str]:
    response = client.models.generate_content(
        model=LLM_MODEL,
        contents=f"Answer in 1-2 factual sentences: {query}",
    )
    answer = response.text
    parts = [s.strip() for s in re.split(r"(?<=[.!?])\s+", answer) if len(s.strip()) > 10]
    return parts or [answer]


# --- 4. Embed ---
def embed_texts(texts: list[str], client: genai.Client) -> list[list[float]]:
    result = client.models.embed_content(
        model=EMBED_MODEL, contents=texts,
        config=types.EmbedContentConfig(task_type="RETRIEVAL_DOCUMENT"),
    )
    return [e.values for e in result.embeddings]


def embed_query(text: str, client: genai.Client) -> list[float]:
    result = client.models.embed_content(
        model=EMBED_MODEL, contents=[text],
        config=types.EmbedContentConfig(task_type="RETRIEVAL_QUERY"),
    )
    return result.embeddings[0].values


# --- 5. Hybrid scoring (max-sim + n-gram boost) ---
def cosine_sim(a, b):
    a, b = np.array(a), np.array(b)
    return float(np.dot(a, b) / (np.linalg.norm(a) * np.linalg.norm(b) + 1e-10))


def extract_ngrams(query: str) -> list[str]:
    words = re.findall(r"\w+", query.lower())
    stop = {"what", "how", "when", "where", "why", "the", "a", "an", "is", "are", "do", "does", "i", "should", "about"}
    words = [w for w in words if w not in stop and len(w) > 2]
    ngrams = list(words)
    for i in range(len(words) - 1):
        ngrams.append(f"{words[i]} {words[i+1]}")
    return ngrams


def score_and_rank(sentences, sent_embeds, hyde_embeds, ngrams):
    results = []
    for i, emb in enumerate(sent_embeds):
        sim = max(cosine_sim(he, emb) for he in hyde_embeds)
        bonus = sum(NGRAM_BOOST for ng in ngrams if ng in sentences[i].lower())
        results.append({"sentence": sentences[i], "score": sim + bonus, "index": i})
    results.sort(key=lambda x: -x["score"])
    return results[:TOP_K]


# --- 6. Extract semantic triples ---
TRIPLES_PROMPT = """Convert these sentences into factual triples. Format: entity | relationship | fact

Rules:
- Subject must be a named entity or specific noun (not pronouns)
- Predicate should be a clear verb phrase in active voice
- Object should be the factual claim or value
- Each triple must be self-contained without context
- One triple per line: subject | predicate | object"""


def extract_triples(query: str, highlights: list[dict], client: genai.Client) -> list[dict]:
    numbered = "\n".join(f"{i+1}. {h['sentence']}" for i, h in enumerate(highlights))
    response = client.models.generate_content(
        model=LLM_MODEL,
        contents=f"Query: {query}\n\nSentences:\n{numbered}",
        config=types.GenerateContentConfig(
            system_instruction=TRIPLES_PROMPT, temperature=0.2,
        ),
    )
    triples = []
    for line in response.text.strip().split("\n"):
        parts = [p.strip() for p in line.split("|")]
        if len(parts) == 3 and all(parts):
            triples.append({"subject": parts[0], "predicate": parts[1], "object": parts[2]})
    return triples


# --- 7. Grounded answer ---
def generate_answer(query: str, triples: list[dict], client: genai.Client) -> str:
    facts = "\n".join(f"- {t['subject']} {t['predicate']} {t['object']}" for t in triples)
    response = client.models.generate_content(
        model=LLM_MODEL,
        contents=f"Question: {query}\n\nFacts:\n{facts}\n\nAnswer based on these facts:",
        config=types.GenerateContentConfig(
            system_instruction=(
                "Answer using ONLY the provided facts. Be concise and factual. "
                "Do not add information beyond what the facts state."
            ),
            temperature=1.0,
        ),
    )
    return response.text


# --- Run it ---
if __name__ == "__main__":
    url = "https://www.vanityfair.com/hollywood/2017/12/the-last-jedi-review"
    query = "What did the reviewer think of The Last Jedi?"

    client = genai.Client(api_key=GEMINI_KEY)

    print("Fetching page...")
    markdown = fetch_page(url)
    print(f"  {len(markdown)} chars")

    print("Splitting sentences...")
    sentences = split_sentences(markdown)
    print(f"  {len(sentences)} sentences")

    print("Generating HyDE vectors...")
    hyde_parts = generate_hyde(query, client)
    print(f"  {len(hyde_parts)} parts")

    print("Embedding...")
    sent_embeds = embed_texts(sentences, client)
    hyde_embeds = [embed_query(p, client) for p in hyde_parts]

    print("Scoring and ranking...")
    ngrams = extract_ngrams(query)
    highlights = score_and_rank(sentences, sent_embeds, hyde_embeds, ngrams)

    print(f"\nTop {len(highlights)} highlights:")
    for h in highlights:
        print(f"  [{h['score']:.3f}] {h['sentence'][:90]}")

    print("\nExtracting triples...")
    triples = extract_triples(query, highlights, client)
    for t in triples:
        print(f"  {t['subject']} | {t['predicate']} | {t['object']}")

    print(f"\nGrounded answer ({sum(len(f'{t[\"subject\"]} {t[\"predicate\"]} {t[\"object\"]}'.split()) for t in triples)} tokens input):")
    answer = generate_answer(query, triples, client)
print(f" {answer}")$ pip install google-genai numpy requests
$ export FIRECRAWL_API_KEY="fc-..."
$ export GEMINI_API_KEY="AI..."
$ python highlights_pipeline.pyYou are a retrieval strategy classifier. Given a user query and a document's
heading structure (each heading has an [ID]), decide the best extraction method.
Strategies:
1. HEADINGS_DIRECT — The heading TEXT itself is a factual answer item
(a product name, a step name). The user wants a LIST and the headings
ARE that list. NEVER use for headings that are questions or topic labels.
2. SECTION_PROSE — The answer is in body text below ONE specific heading.
ONLY use when highly confident the query maps to a single section.
NEVER use for broad queries like "tell me about X" or overviews.
3. FULL_EXTRACTION — The default when in doubt. Broad queries, opinions,
summaries, or anything spanning multiple sections.
4. FULL_EXTRACTION_TRIPLES — Scattered facts needing entity disambiguation
(reviews, comparisons, multi-entity content).
When unsure, prefer FULL_EXTRACTION over SECTION_PROSE.
Format:
STRATEGY: <name>
IDS: <comma-separated heading IDs, or N/A>
REASON: <one sentence>Convert these sentences into factual triples.
Format: entity | relationship | fact
Rules:
- Subject must be a named entity or specific noun (not pronouns)
- Predicate should be a clear verb phrase in active voice
- Object should be the factual claim or value
- Each triple must be self-contained without context
- One triple per line: subject | predicate | objectTry it yourself (demo)
Select a page, ask a question. The pipeline fetches, classifies, splits, embeds, ranks, extracts, and generates in real-time. The classifier badge shows which strategy was selected and why. Pre-cached pages return in ~3 seconds. Custom URLs in 5-15 seconds.
Every highlight is scored. Every triple is structured. Every answer is grounded. The classifier's reasoning is visible. No magic.
Use the inline version below (warning: it gets a bit expandy once the results come in), or click here to open the full demo in a new tab.
Limitations (or: what I'd do next)
This is a proof-of-concept built in a few days. It validates the architecture and demonstrates the approach, but a production system would need work in several areas.
Polarity blindness
"301 redirects are great for SEO" and "301 redirects are terrible for SEO" have nearly identical embeddings. The retrieval layer can't distinguish stance, it only sees topic similarity. Counter-arguments, sarcasm, and negation are invisible to cosine similarity. A trained re-ranker or negation detection heuristics would help here.
The keyword boost trade-off
N-gram boosting helps surface sentences containing query terms. But for factual lookups, it can over-weight sentences that repeat the question over sentences that contain the answer. "The Weesp train disaster took place near Weesp" matches more query n-grams than "With 41 deaths and 42 injuries" — even though the latter is what you need. A trained re-ranker would learn this balance; our fixed boost weight can't.
Latency on large pages
Wikipedia's OpenAI article (19,759 words, 1,041 sentences) took 68 seconds to embed, our worst case by far. The classifier's section route sidesteps this, but if the classifier routes to FULL_EXTRACTION on a massive page you might as well stick the kettle on. Pre-computed embeddings (like Exa's approach) eliminate this entirely. For a production system, you'd index at crawl time and look up at query time.
Clause extraction is regex, not a model
Our clause boundary detection uses verb-pattern matching — find the declarative verb, extract the complement. It's an 80/20 approximation. A trained sequence labeller would find better boundaries, handle edge cases, and avoid the occasional awkward extraction. Exa likely has something more sophisticated here.
Content access
Live scraping at query time hits content gates, cookie walls, and dead links. Exa avoids this by pre-crawling and indexing billions of pages. For ad-hoc URLs this is unavoidable; for a production pipeline you'd pre-crawl.
The SimpleQA caveat
Our 75% accuracy comes from 40 questions. It's enough to show the pattern but not statistically rigorous. The remaining 15-point gap to Exa's reported 90% is attributable to fine-tuned embeddings, a trained re-ranker, a frontier model for answer generation, and pre-indexed content. None of those are architectural differences. They're optimization layers on top of what's likely a similar pipeline.
What this means (and why I did it)
Exa's search is great. In no way am I saying otherwise. They find relevant pages fast, at scale, with impressive latency. Their indexing infrastructure — billions of pages, pre-computed embeddings, sub-second retrieval — is real engineering that's worth paying for.
But their "highlights" feature, as delivered via the API doesn't really seem to be doing what the demo suggests (and what I based V1 of my simulation on). On unstructured prose, the gap between the demo and the API output becomes pretty clear.
What they should be doing — and what their "trained model" is presumably aspiring to — is exactly the kind of adaptive routing in our pipeline: understand the page structure, understand the query intent, pick the right extraction strategy. On a listicle, grab headings. On a FAQ, grab the relevant section. On a review, extract and compress opinions from across the full article.
I built that in a few days with off-the-shelf tools and a transparent, auditable pipeline. A potato and some string. But it's a proof-of-concept, not a production system and the limitations section above is honest about where it falls short. It will probably fail spectacularly in some cases. But hey, I'm just one guy, and every decision is visible: which strategy was chosen, why, what was extracted, how it scored, and how the final answer was grounded.
Why did I do it?
I've been asking myself the same question.
What was going to be a quick mess around to see if I could figure out what they were doing... well it escalated quickly.
But the answer is: this is search and retrieval. And as an SEO, I like to reverse engineer these things. I don't like magic. I don't like black boxes. And I've also spent the past year or so deep in the trenches with this stuff while working on QueryBurst, experimenting with all manners of retrieval, so I had a fair idea what they were doing as soon as I saw the demo.
I also think this also has some wider implications, particularly for some of the arguments put forward by the GEO crowd. I'll likely put out a follow up post later in the week covering that.
So if you want to find out what those implication are... well, there's a big box down below where you can pop your email in to subscribe.
And once you do, you can try out the full demo pipeline here.
*All Exa API tests were conducted between 9th and 11th May, 2026, using the latest exa-py SDK (v2.12.1) with both the Python SDK and their web dashboard. Request IDs are preserved for verification.
**No potatoes were harmed in the making of this blog post.