QueryBurst Answer Engine
Create multiple customer personas with real history and context. Build multi-step, branching conversations that map the buyer journey from first question to final recommendation. Smash open the black box of AI search.
Answer Engine from $49/mo · Full platform from $149/mo
So what does that actually mean? Good question. Allow us to show you.
Click the buttons — you won’t break anything.
What does Answer Engine actually do?
You want the elevator pitch? QueryBurst Answer Engine lets you model and observe how AI answers are actually produced in the real world. Every answer from our LLM overlords is shaped by the person asking, what the system already knows about them, the conversation so far, the model’s prior knowledge, the sources it retrieves, and what evidence it ultimately chooses to use. We built all of that in.
Change one of those inputs and the output changes.
Oh yeah, and the prompt. We forgot the “prompt”.
But that’s probably the least interesting bit.
So this is like prompt tracking then?
Can you read? No. A prompt is only a small part of what causes an answer to be an answer. Two people can ask exactly the same question, exact same words, and get completely different responses.
Prompt trackers try and solve that with synthetic mega-prompts. You know, those ones you’ve seen in your GSC like:
But that’s not how the Force works. That’s not how any of this works. You can’t just inject a person’s entire life story into a single message and call it a day.
With QueryBurst Answer Engine a “prompt” could literally be:
“What tool should I buy?”
And because when you sign up (you will be signing up right?) the first thing you’re going to do is set up personas (with history), the system is going to know what “tool” means and who “I” is.
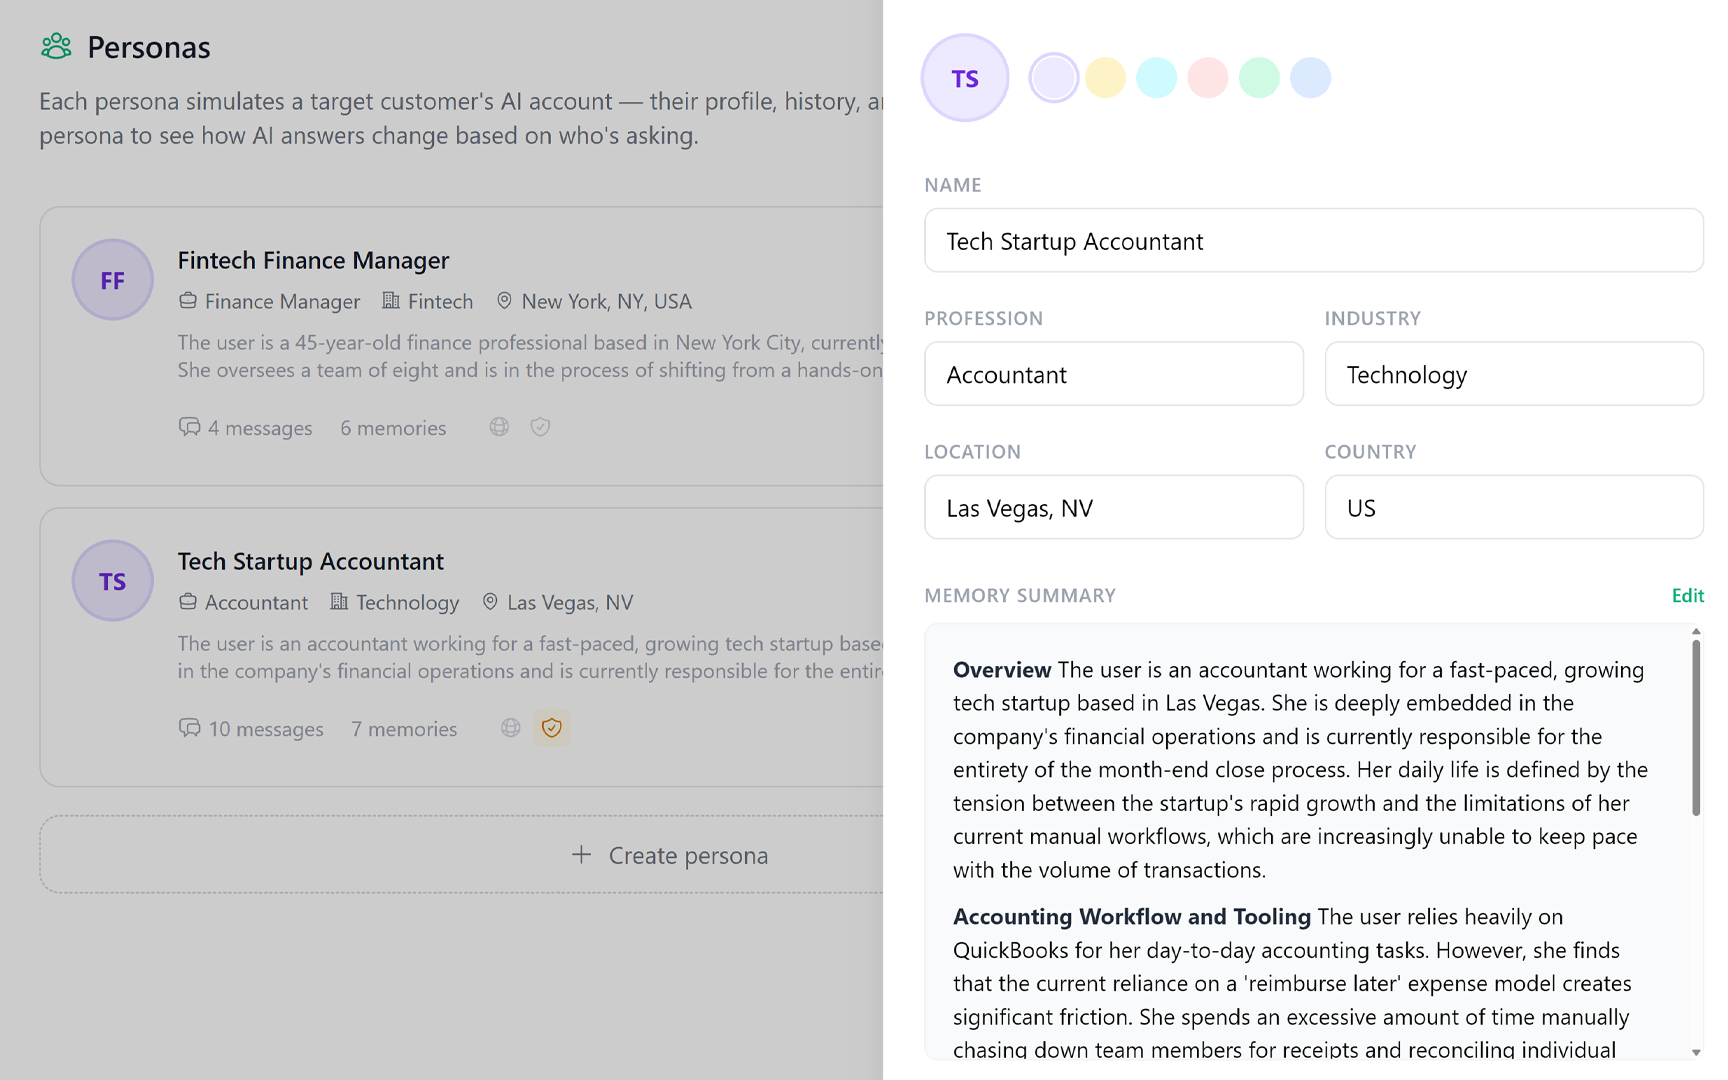
And then you can ask a follow-up:
“What’s the cheapest?”
And then you can branch it into different paths (but we’ll get to that).
Prompt trackers can’t do any of that (there are actually technical reasons why they can’t), and that’s how people actually talk to AI.
But after personas I’m still setting up prompts right?
You need to stop thinking in prompts dude. Seriously. No, you’ll be setting up C-O-N-V-E-R-S-A-T-I-O-N-S.
You know, the thing the prompt trackers have been screaming for the past 2 years…
“people don’t search using keywords anymore, they have conversations”.
Well yeah, we agree (shame they didn’t listen to their own advice).
Which is why the main thing you’ll be setting up (after people) is buyer journeys. That could look something like:
“Do I need a lawyer?” turn 1 — the persona has context on an “accident”, no need to restate it
“Who’s the best near me?” turn 2 — the persona has context on their location + this turn has the context of the answer from turn 1
“Do I get a free consultation?”
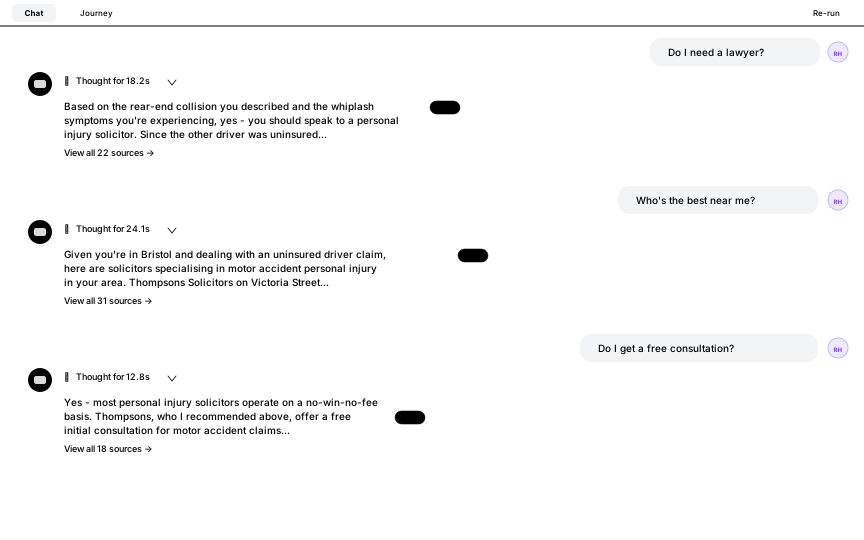
Would any of those questions work with a prompt tracker? No, because the first turn relies on the user context and the subsequent turns rely on the previous answers.
See?
(we haven’t got into branching yet btw)
That sounds complicated…
Can you use ChatGPT? Do you know how to type words into a box? Well, you can set up a buyer journey then. Because the setup is a literal chat window. Because a conversation is a chat.
You were expecting something more complicated? SMH.
Doesn’t sound like there’s much depth to it…
Oh so now you want complexity do you? Alright then…
Every message runs through an 8-stage retrieval pipeline.
First, the model forms a pre-retrieval prior — what it currently thinks the answer is likely to be before searching, based on the person asking, their history, and the conversation so far.
That prior then shapes the fan-out. Answer Engine decomposes the question into thematically grouped sub-queries, each with its own HyDE target: an answer-shaped hypothetical document used as a semantic anchor for retrieval.
So you’re not just seeing what it searched for. You can inspect the hypothesis that made those searches relevant in the first place.
Those searches are then dispatched to the Brave LLM Context API, geo-targeted using the persona’s country and language.
The retrieved evidence can optionally be merged with content from your own crawled site, letting you bypass discovery and test how your pages compete once they’re inside the candidate set.
From there, Answer Engine extracts entities, relationships and key concepts across the evidence pool, reranks the candidates against the original question, applies configurable selection thresholds, and decides what survives into grounding.
Grounding then maps factual claims in the final response back to their source documents, with character-level span references.
And the source funnel lets you trace any individual page all the way through:
So if your page was found but never made the answer, you can see where it dropped out instead of staring at a citation count and making up a story about why.
All of that sits inside a DAG-based conversation model where every branch inherits its own state, up to five paths can be compared side-by-side, reruns expose answer drift across generations, and the full trace can be exported as structured data.
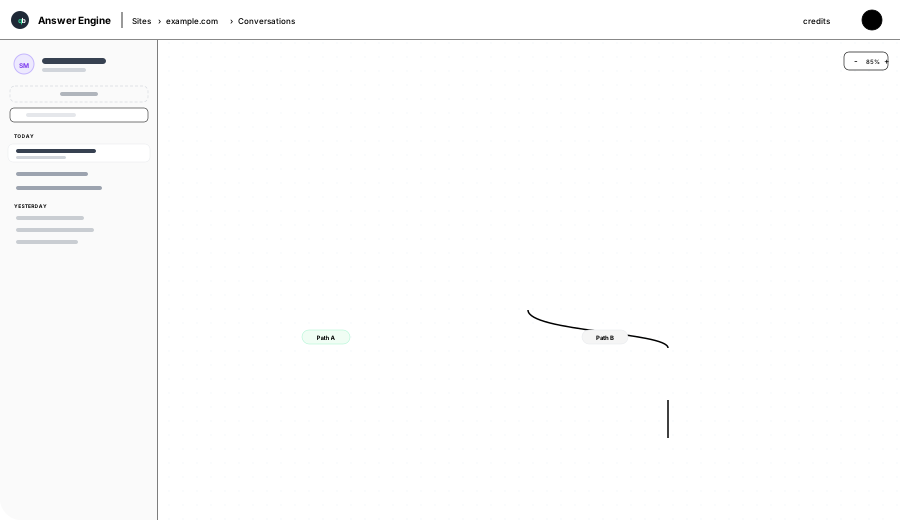
So this is a simulation then? It’s not real answers like prompt trackers?
That’s a good question. And yes, Answer Engine models the behind-the-scenes mechanics of modern AI systems.
But let’s unpack this a little.
Because while the prompt trackers do scrape the UI of the AI providers, and the answers are “real” in that sense, we wouldn’t conflate this with them necessarily being a faithful representation of what an actual human being sees.
We’ve already covered user/conversation context and synthetic mega-prompts.
But there’s another layer here: the prompt trackers scrape the free, logged-out versions of each provider. And even the simple action of logging in can drastically change the reasoning budget, the fan-outs, and everything else up/downstream.
Do we really think someone’s opening up an incognito browser, typing in chatgpt.com and asking in a single turn:
“Which CRM should I buy?”
Maybe someone does. But we doubt it’s the most common use case.
Let’s not labor on this, but we’ll quickly tackle the common “API is not representative of what the user sees!”
And this is correct. If you’re just sending raw requests to the API.
It’s up to you to build the harness around the API. And that’s what we’ve done. A harness that mirrors our current understanding of what ChatGPT et al are doing in their pipelines (we’ve done a lot of research on all this…)
So we’re not just sending:
“Which CRM should I buy?”
to OpenAI and hoping for the best. We’re doing everything we already covered above.
And it’s only by modelling the process forwards rather than backwards that you can do all the cool things that we’ll cover below.
But my prompt tracker already shows me the fan-outs?
Useful to know. But that’s the what, not the why.
In Answer Engine, the fan-outs don’t float around on their own. You can inspect the pre-retrieval prior that came before them — the model’s initial view of what a useful answer should look like, shaped by the person, their history, and the conversation so far.
That initial HyDE answer is then decomposed into targeted fan-outs: effectively, the model breaking its answer-shaped hypothesis into the things it needs to go and verify or complete.
And each fan-out gets its own HyDE target — what the model expects the ideal piece of evidence for that search to look like.
So you get three layers of observability:
What is it looking for? — the fan-out
Why is it looking for it? — the original pre-retrieval prior
What does it expect to find? — the HyDE target for that individual fan-out
That’s quite a bit more useful than a list of searches.
And then there’s another question we care about:
Were you already in the answer before retrieval even started?
If your brand, product, competitor, or entity appears in that pre-retrieval prior, Answer Engine can show you that too.
From there, you can follow it through the entire chain:
Maybe you were already part of the model’s initial answer-shaped hypothesis.
Maybe you weren’t in the prior, but retrieval brought you into the candidate set.
Maybe you were retrieved, but lost during selection.
Maybe you survived selection and were used to ground the answer, but never received a visible citation.
Or maybe you made it all the way through.
That’s the difference between knowing what the final answer looked like and being able to inspect where you entered the process, where you survived, and where you dropped out.
And if all your prompt tracker can tell you is “you weren’t cited”, well…
We’ve got a few more questions to ask.
What if I run the exact same question as a different persona?
This is where the fun begins…
Change the person and you can change the prior.
Change the prior and you can change the fan-outs.
Change the fan-outs and you can change the evidence retrieved.
And before you know it, two people who typed the exact same words are heading toward completely different answers.
That’s what actually happens out there in the real world. And it’s why we keep banging on about the fact that the prompt is not the whole input.
Can I compare paths?
Of course.
Branch at any turn, follow a different answer, introduce a different constraint, or simply ask a different follow-up.
Then inspect how those paths diverge:
Prior? Fan-out? Source selection? Grounding? Final answer?
That’s a buyer journey you can actually inspect.
And if you want to test the same question with a completely different persona, you can run it separately and see how the research path and answer change.
Can I rerun a conversation?
You can run a conversation as many times as you want (each message in a conversation uses one credit).
But we’d recommend rerunning once a month, or when you think something meaningful has actually changed (a new model, fine-tune, search ranking shift, retrieval behavior, etc).
Otherwise, you’re getting back into observing noise.
If you do want a daily baseline, this is probably where your prompt tracker can live in harmony with Answer Engine (see, we’re not completely dogmatic).
[We keep a close eye on how the models are behaving, particularly around fan-out and retrieval, so there’s always some tweaking at our end to keep the pipeline aligned as closely as possible with current observed behavior.]
Because Answer Engine keeps the intermediate states, you can see what actually changed between runs.
Maybe the answer changed because the prior shifted.
Maybe the searches changed.
Maybe the same sources were retrieved, but a different snippet won selection.
Maybe nothing upstream changed and the final generation simply varied.
“The line went down” suddenly becomes a much less interesting observation.
What if my page gets retrieved but doesn’t make the final answer?
Good. Now we’re asking useful questions.
Getting retrieved is not the same thing as getting selected.
Answer Engine lets you see whether your page entered the candidate set, how strongly it matched the retrieval target, whether it survived reranking, whether it was used during grounding, and whether it ultimately received a citation.
So instead of:
“We weren’t cited.”
You can ask:
“Where did we drop out?”
Maybe the page was never retrieved.
Maybe it was retrieved but another source was a better fit for the information the model was looking for.
Maybe it survived selection but didn’t support any of the claims that made the final answer.
Maybe it helped ground the response but never got the shiny little citation badge.
Those are very different problems.
Can I test whether my page would have survived if it had been found?
Yep.
You can inject one of your own crawled pages directly into the candidate set for a message.
That deliberately bypasses discovery.
So now you can ask a much cleaner question:
If the system had found this page, would it actually have been good enough to survive selection and grounding?
If the answer is no, then “we just need better crawlability” probably isn’t your problem.
If it makes it all the way through, then discovery becomes a much more interesting thing to investigate.
It’s basically a counterfactual test for your content.
Can I see why another source beat mine?
That’s rather the point.
You can inspect the evidence that survived, the passages that were selected, the entities and claims being surfaced, and the information requirement each source was effectively satisfying.
So instead of looking at a competitor citation and thinking:
“Cool. Better write what they wrote.”
you can ask:
“What job was this source doing in the answer that mine wasn’t?”
That might be clearer evidence.
Better topical fit.
A claim you don’t make.
A relationship your site doesn’t communicate.
A detail that’s buried three scrolls down your page.
Or simply a stronger passage for the thing the model was trying to verify.
Can I compare what the model wanted with what my site actually says?
Now you’re getting dangerously close to the rest of QueryBurst.
Answer Engine shows you what the research process was looking for.
Site Intelligence shows you what your website actually communicates across its entities, claims, relationships and topics.
Put the two together and you can start asking much more useful questions:
Does the site contain the information?
Is it stated clearly?
Is it attached to the right entity?
Is another page contradicting it?
Can the system retrieve it?
Does it survive selection when it does?
Which is a bit more actionable than “your AI visibility score fell 3.7%”.
And then I can actually fix it?
That’s the idea.
Answer Engine is the investigation layer.
Once you know where the chain broke, you can move into the wider QueryBurst toolkit to work on the actual problem.
Retrieval issue? Optimizer or Content Lab.
Conflicting facts? Facts & Claims / Verify.
Weak recommendation criteria? Answer Spy / Criteria Investigator.
Site-wide entity or relationship problem? Site Intelligence.
Agent can’t find the information? Agent Discovery.
You don’t need another dashboard telling you something happened.
You need to know what happened, where it happened, and what you can do about it.
They don’t inspect the engine.
What does Answer Engine do?
Answer Engine models the buyer journey through AI search. Create customer personas — real archetypes with context, not one-size-fits-all prompts — and build multi-turn conversations that follow the path from first question to final recommendation.
At every step, you can see what the AI model searched for, what it found, and why it chose what it chose. Think of it as journey mapping, but for AI conversations.
How do I model a buyer journey?
Start with the persona — who’s asking the question. A VP evaluating CRM tools and an intern told to “look into project management” are on completely different journeys. Set up the persona’s context, then start the conversation the way a real customer would: broad, exploratory, getting more specific as they go.
Each turn narrows the funnel. Branch the conversation to model different paths through the same stage — “compare on price” vs. “compare on integrations”. You’re building a map of how different buyer profiles navigate AI recommendations.
What happens over multiple turns?
Context accumulates. The first question sets the direction. By turn three, the AI model has a position. By turn seven, it’s making recommendations shaped by everything that came before.
Ask “how much is it?” at the end of a conversation about enterprise CRM, and the model retrieves enterprise pricing pages. Ask the same question after discussing freelance tools, and it retrieves something completely different. Multi-turn is how your customers actually use AI search. Answer Engine lets you model that.
Can I compare different buyer paths?
Branch the conversation at any turn and compare where the paths diverge. One buyer asks about price. Another asks about integrations. A third asks what their competitors use. Each branch runs independently with its own evidence trail.
Compare up to 5 paths side-by-side to see which questions lead to which recommendations — and where your content appears or disappears from the AI’s consideration set.
Where do they actually diverge?
At the evidence layer. Two paths might produce the same recommendation on the surface, but the reasons are different — different sources cited, different claims highlighted, different competitors mentioned.
The divergence isn’t just what the AI said. It’s what it read, what it selected, and what it ignored. That’s where your content strategy gaps live.
What if the AI recommends a competitor?
Then you know exactly why. Open the source trail — see which pages the model retrieved, which claims it extracted, and how it weighted them. If a competitor’s comparison page is outranking your product page in the AI’s evidence selection, you can see it. If a review site ranking your competitor first is driving the recommendation, you can see that too.
It’s not about suppressing competitors. It’s about understanding the evidence the AI is actually using.
Can I see which content to fix?
That’s what Site Intelligence is for. Answer Engine shows you the conversation and the evidence. Site Intelligence crawls your actual site and maps the entities, claims, and topics AI models are extracting.
Cross-reference the two: if Answer Engine shows the model citing a claim you never made, Site Intelligence shows you where to make it. The Toolkit gives you the optimisation tools to close the gap.
They don’t inspect the engine.
Show me the big picture.
What does Answer Engine do?
It lets you see what AI says about your business — and why. Ask it the questions your customers would ask (“who’s the best accountant in Bristol?” or “which consultancy should I use?”) and watch how AI search builds its answer.
You’ll see where it looks, what it reads, and why it recommends who it recommends. If you can use ChatGPT, you can use this.
Can I just ask it a question?
Yes. Set up a quick profile of your typical customer (who they are, what they’re looking for), type a question, and watch what happens. You’ll see the answer, and you’ll see exactly where that answer came from — which websites it read, which claims it picked out, which competitors it mentioned.
No setup wizards. No 47-step onboarding. One persona, one question, one set of answers you can actually read.
What if I want to go deeper?
It’s all there when you want it. Ask follow-up questions and watch how the answers change — the AI remembers the conversation. Branch off to explore different paths (“what if they ask about price?” vs. “what if they ask about reviews?”).
Every answer has a “show me the sources” button if you want to see exactly where the information came from. Go as deep as you like, or just read the answers. It works either way.
What does it cost?
Answer Engine starts at $49/mo with 150 messages on the Starter plan. Want Site Intelligence, the AI Search Toolkit, and everything else? Full platform access from $149/mo. The only difference between tiers is monthly message credits — each message runs a full pipeline. Top up as needed; purchased credits roll over.
No feature gates on Pro and above, no add-on pricing, no enterprise-only stages.
Stop tracking the answer.
Start inspecting the engine.
View plans
Answer Engine from $49/mo · Full platform from $149/mo